무슨 발표인가
- Triton Inference Server의 후속 오픈소스 추론 소프트웨어
- 수천 개 GPU 규모의 추론 통신 오케스트레이션·가속화
- 처리·생성 단계를 분리해 각 단계별 독립 최적화 가능
현재 이용 가능
원문 (영어)
GTC— NVIDIA today unveiled NVIDIA Dynamo , an open-source inference software for accelerating and scaling AI reasoning models in AI factories at the lowest cost and with the highest efficiency. Efficiently orchestrating and coordinating AI inference requests across a large fleet of GPUs is crucial to ensuring that AI factories run at the lowest possible cost to maximize token revenue generation.
As AI reasoning goes mainstream, every AI model will generate tens of thousands of tokens used to “think” with every prompt. Increasing inference performance while continually lowering the cost of inference accelerates growth and boosts revenue opportunities for service providers.
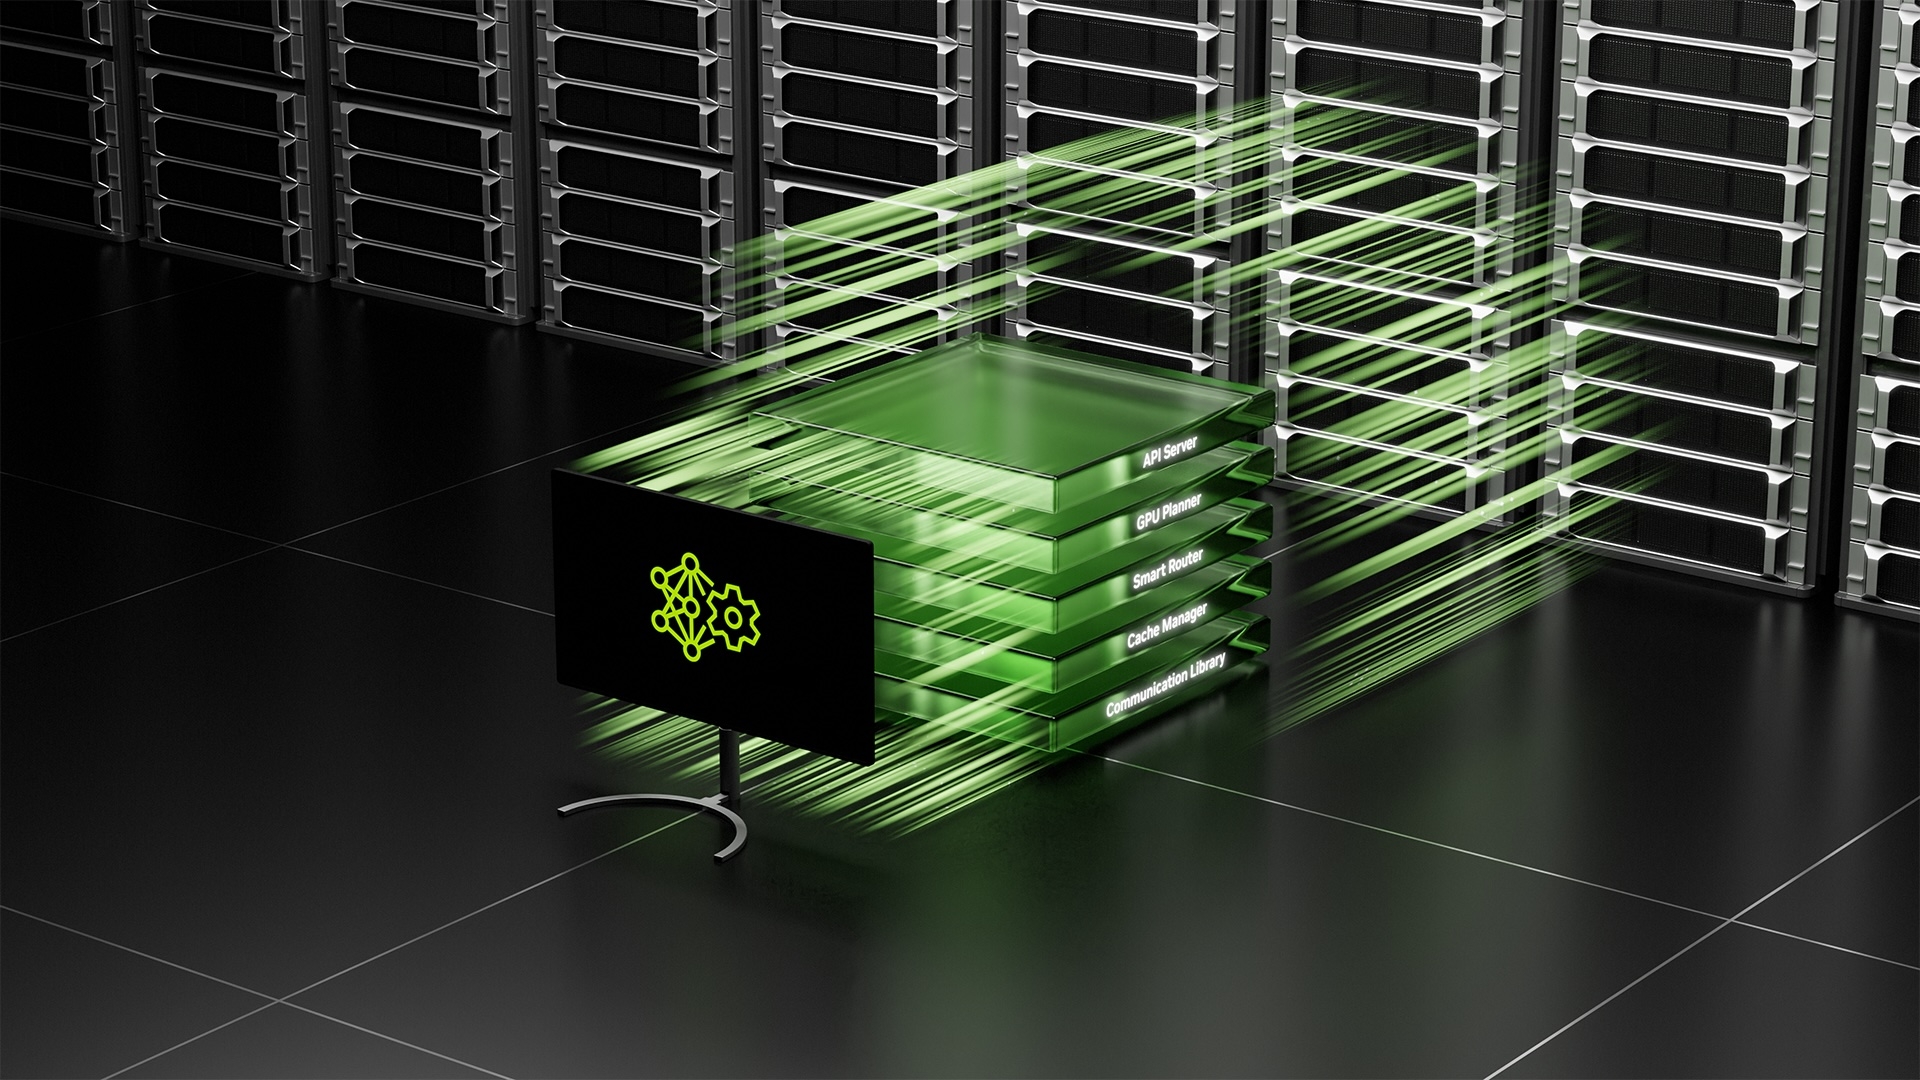
NVIDIA Dynamo, the successor to NVIDIA Triton Inference Server , is new AI inference-serving software designed to maximize token revenue generation for AI factories deploying reasoning AI models. It orchestrates and accelerates inference communication across thousands of GPUs, and uses disaggregated serving to separate the processing and generation phases of large language models (LLMs) on different GPUs.
This allows each phase to be optimized independently for its specific needs and ensures maximum GPU resource utilization. “Industries around the world are training AI models to think and learn in different ways, making them more sophisticated over time,” said Jensen Huang, founder and CEO of NVIDIA.
“To enable a future of custom reasoning AI, NVIDIA Dynamo helps serve these models at scale, driving cost savings and efficiencies across AI factories.” Using the same number of GPUs, Dynamo doubles the performance and revenue of AI factories serving Llama models on today’s NVIDIA Hopper platform.
원문: NVIDIA News — "NVIDIA Dynamo Open-Source Library Accelerates and Scales AI Reasoning Models" (2025-07-03) 공식 원문: https://nvidianews.nvidia.com/news/nvidia-dynamo-open-source-library-accelerates-and-scales-ai-reasoning-models